A DataFrame is an immutable distributed collection of data like an RDD, but unlike an RDD, data is organized into named columns of a table in a relational database. This makes processing easier by imposing a structure onto a distributed collection of data. From Spark 2.0 onwards, … Read more...
800+ Java & Big Data Interview Q&As
130+ job offers to choose from as a self-taught Java & Big Data contractor for 22+ years. It pays to prepare.
Blog Archives
06: Apache Kafka Streaming with JSON & Java Tutorial – stateful operations groupByKey, windowing & aggregate
This extends Apache Kafka Streaming with JSON & Java Tutorial and you can either use Kafka on Docker as per Apache Kafka example with Java – getting started tutorial or install Kafka on Mac (i.e Getting started with Apache Kafka on Mac Tutorial) or Windows. … Read more ›...
06: Apache Spark standalone cluster on Docker to read from AWS S3 bucket

This extends Apache Spark local mode read from AWS S3 bucket with Docker. Step 1: The “docker-compose.yml” with minio to emulate AWS S3, Spark master and Spark worker to form a cluster.
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 76 77 78 79 80 81 82 83 84 85 |
version: "2" services: s3: container_name: s3 image: minio/minio:RELEASE.2018-05-04T23-13-12Z environment: MINIO_ACCESS_KEY: user MINIO_SECRET_KEY: password ports: - 9000:9000 volumes: - ./docker/s3/data:/data - ./docker/s3/config:/root/.minio networks: - infra command: server /data spark-master: build: dockerfile: spark.dockerfile context: ./docker/spark command: bin/spark-class org.apache.spark.deploy.master.Master -h spark-master hostname: spark-master environment: MASTER: spark://spark-master:7077 SPARK_CONF_DIR: /conf SPARK_PUBLIC_DNS: 127.0.0.1 expose: - 7001 - 7002 - 7003 - 7004 - 7005 - 7006 - 7077 - 6066 - 5005 ports: - 5005:5005 - 6066:6066 - 7077:7077 - 8080:8080 volumes: - ./docker/spark/spark-master:/conf - ./data:/tmp/data networks: - infra spark-worker-1: build: dockerfile: spark.dockerfile context: ./docker/spark command: bin/spark-class org.apache.spark.deploy.worker.Worker spark://spark-master:7077 hostname: spark-worker-1 environment: SPARK_CONF_DIR: /conf SPARK_PUBLIC_DNS: 127.0.0.1 SPARK_WORKER_CORES: 2 SPARK_WORKER_MEMORY: 2g SPARK_WORKER_PORT: 8881 SPARK_WORKER_WEBUI_PORT: 8081 links: - spark-master expose: - 7012 - 7013 - 7014 - 7015 - 7016 - 8881 ports: - 8081:8081 volumes: - ./conf/spark-worker-1:/conf - ./data:/tmp/data networks: - infra networks: infra: external: name: docker_test_infra |
Step 2: The “ … Read more ›...
06: Avro Schema evolution tutorial
Q1. What do you understand by the term “AVRO schema evolution“?
A1. Schema evolution is the term used for how the store behaves when Avro schema is changed after data has been written to the store using an older version of that schema.
…
06: Databricks – Spark Window functions

Prerequisite: Extends Databricks getting started – Spark, Shell, SQL. What is a window function? Q. What are the different types of functions in Spark SQL? A. There are 4 types of functions: 1) Built-in functions: from org.apache.spark.sql. … Read more ›...
06: Learn how to access Hive from Spark via SparkSQL & Dataframes by example
These Hadoop tutorials assume that you have installed Cloudera QuickStart, which has the Hadoop eco system like HDFS, Spark, Hive, HBase, YARN, etc. This example extends Learn Hive to write to and read from AVRO & Parquet files by examples to access Hive metastore via Spark SQL. … Read more...
06: Setting up Spark-shell on Mac & getting started
This tutorial outlines the basic steps to get started with Spark on Mac OS. 1. Install Xcode Xcode can be installed via Apple appstore. Xcode is Apple’s Integrated Development Environment (IDE). Xcode is a large suite of software development tools and libraries from Apple. 2.… Read more ›...
06: Spark on Zeppelin – RDD operation zipWithIndex
Pre-requisite: Docker is installed on your machine for Mac OS X (E.g. $ brew cask install docker) or Windows 10. Docker interview Q&As. This extends setting up Apache Zeppelin Notebook. Q. Why do we need zipWithIndex? A. … Read more ›...
06: Spark Streaming with Flume Avro Sink Tutorial
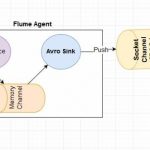
This extends Running a Simple Spark Job in local & cluster modes and Apache Flume with JMS source (Websphere MQ) and HDFS sink. In this tutorial a Flume sink will ingest the data from a source like JMS, HDFS, etc and pass it to an “ … Read more ›...
07: Apache Kafka Streaming with stateless operations
This extends 06: Apache Kafka Streaming with JSON & Java Tutorial – stateful operations groupByKey, windowing & aggregate and Getting started with Apache Kafka on Mac Tutorial.
Kafka Streams DSL (i.e. Domain Specific Language) is built on top of the Streams Processor API.
…
07: Apache Spark standalone cluster on Docker to read from & write to AWS S3 bucket

This extends Apache Spark local mode read from AWS S3 bucket with Docker. Step 1: The “docker-compose.yml” with minio to emulate AWS S3, Spark master and Spark worker to form a cluster.
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 22 23 24 25 26 27 28 29 30 31 32 33 34 35 36 37 38 39 40 41 42 43 44 45 46 47 48 49 50 51 52 53 54 55 56 57 58 59 60 61 62 63 64 65 66 67 68 69 70 71 72 73 74 75 76 77 78 79 80 81 82 83 84 85 |
version: "2" services: s3: container_name: s3 image: minio/minio:RELEASE.2018-05-04T23-13-12Z environment: MINIO_ACCESS_KEY: user MINIO_SECRET_KEY: password ports: - 9000:9000 volumes: - ./docker/s3/data:/data - ./docker/s3/config:/root/.minio networks: - infra command: server /data spark-master: build: dockerfile: spark.dockerfile context: ./docker/spark command: bin/spark-class org.apache.spark.deploy.master.Master -h spark-master hostname: spark-master environment: MASTER: spark://spark-master:7077 SPARK_CONF_DIR: /conf SPARK_PUBLIC_DNS: 127.0.0.1 expose: - 7001 - 7002 - 7003 - 7004 - 7005 - 7006 - 7077 - 6066 - 5005 ports: - 5005:5005 - 6066:6066 - 7077:7077 - 8080:8080 volumes: - ./docker/spark/spark-master:/conf - ./data:/tmp/data networks: - infra spark-worker-1: build: dockerfile: spark.dockerfile context: ./docker/spark command: bin/spark-class org.apache.spark.deploy.worker.Worker spark://spark-master:7077 hostname: spark-worker-1 environment: SPARK_CONF_DIR: /conf SPARK_PUBLIC_DNS: 127.0.0.1 SPARK_WORKER_CORES: 2 SPARK_WORKER_MEMORY: 2g SPARK_WORKER_PORT: 8881 SPARK_WORKER_WEBUI_PORT: 8081 links: - spark-master expose: - 7012 - 7013 - 7014 - 7015 - 7016 - 8881 ports: - 8081:8081 volumes: - ./conf/spark-worker-1:/conf - ./data:/tmp/data networks: - infra networks: infra: external: name: docker_test_infra |
Step 2: The “ … Read more ›...
07: Avro IDL (e.g. avdl) to Java objects & Avro Schemas (i.e. avsc) tutorial
Avro IDL (i.e Interface Definition Language) schema can be specified with two type of files “avpr” (i.e. AVro PRotocol file) & “avdl” (i.e. AVro iDL). Step 1: Create a maven based Java project from a command-line
|
1 |
$ mvn archetype:generate -B -DgroupId=com.mytutorial -DartifactId=simple-avro |
Step 2: Import it into eclipse as a maven project. … Read more...
07: Databricks – groupBy, collect_list & explode

Prerequisite: Extends Databricks – Spark Window functions. Step 1: Create a new Python notebook, and attach it to a cluster. Step 2: Let’s create some data using pyspark.
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 |
emp_list = ( (1, 'John', 'Java'), (2, 'Peter', 'Scala'), (2, 'Peter', 'Python'), (2, 'Peter', 'Spark'), (1, 'John', 'JEE'), (6, 'Elliot', 'Unix',) ) data_schema = [StructField('emp_id', IntegerType(), False), StructField('emp_name', StringType(), False), StructField('emp_expertise', StringType(), False)] final_struc = StructType(fields=data_schema) df = spark.sparkContext.parallelize(emp_list); emp_df = spark.createDataFrame(df, final_struc) emp_df.show() |
Output:
|
1 2 3 4 5 6 7 8 9 10 11 |
+------+--------+-------------+ |emp_id|emp_name|emp_expertise| +------+--------+-------------+ | 1| John| Java| | 2| Peter| Scala| | 2| Peter| Python| | 2| Peter| Spark| | 1| John| JEE| | 6| Elliot| Unix| +------+--------+-------------+ |
agg( ) &… Read more ›...
Top