This extends 50+ SQL scenarios based interview Q&As – identifying consecutive records – job status repetition. A popular SQL coding interview question. Setup the data on db-fiddle MySQL V8.0 to practice. Q. Given the below input, how will you list user_id & … Read more ›...
800+ Java & Big Data Interview Q&As
130+ job offers to choose from as a self-taught Java & Big Data contractor for 22+ years. It pays to prepare.
Blog Archives
29: 50+ SQL scenarios based interview Q&As – Non-Equi Join problem
Q01. What is a Non-Equi Join? A01. A Non-Equi Join in SQL that uses operators other than equality operator (i.e. ‘=’), like , = to join two tables. Q02. When to use a Non-Equi Join? … Read more ›...
This content is for 30-Day-Full-Access, 100-Day-Full-Access, 200-Day-Full-Access, and 365-Day-Full-Access members only.
Register
80+ Free Java FAQs
80+ Free Big Data FAQs
Already a member? Log in here
30: 50+ SQL scenarios based interview Q&As – Data cleaning, quality checks & profiling
This post covers SQL examples to perform quality checks, clean data and profile data. Q01. What is Data Cleaning? Can SQL do data cleaning? A01. Data cleaning is the process of fixing bad data. … Read more ›...
This content is for 30-Day-Full-Access, 100-Day-Full-Access, 200-Day-Full-Access, and 365-Day-Full-Access members only.
Register
80+ Free Java FAQs
80+ Free Big Data FAQs
Already a member? Log in here
31: 50+ SQL scenarios based interview Q&As – Finding records from first table where no match found in second table
Setup the data on db-fiddle MySQL V9.0 to practice. There are business scenarios for:
1) Finding records in the first table where matching records are found in the second table are shown in the output. This can be done with a semi-join.
…
32: 50+ SQL scenarios based interview Q&As – use of unpivot, lag(..), row_num(..), cumulative sum() and CTE
Setup the data on db-fiddle MySQL V9.0 to practice. Make sure to select latest MySQL version to ensure Common Table Expressions (i.e CTE) is supported. This is not a real life scenario problem, but a simple example that uses many of the SQL syntaxes & techniques. … Read more ›...
This content is for 30-Day-Full-Access, 100-Day-Full-Access, 200-Day-Full-Access, and 365-Day-Full-Access members only.
Register
80+ Free Java FAQs
80+ Free Big Data FAQs
Already a member? Log in here
33: 50+ SQL scenarios based interview Q&As – Nuances of NULL in SQL
NULL is a special marker used in SQL to indicate that a data value does not exist in the database.
Setup the data on db-fiddle MySQL V9.0 to practice. Make sure to select latest MySQL version to ensure Common Table Expressions (i.e CTE) is supported.
…
5 Amazon EMR Vs. Cloudera interview Q&As

Q1. What is Amazon EMR? A1. EMR stands for Elastic Map Reduce, which is an Amazon Web Services (AWS) tool for big data processing and analysis. Amazon EMR offers elastic, cost-effective, and expandable low-configuration service as an alternative to running an on premise or EC2 cloude based Hadoop cluster (E.g....
This content is for 30-Day-Full-Access, 100-Day-Full-Access, 200-Day-Full-Access, and 365-Day-Full-Access members only.
Register
80+ Free Java FAQs
80+ Free Big Data FAQs
Already a member? Log in here
5 Apache YARN interview Q&As

Q1. What is Apache YARN? A1. Apache Hadoop YARN (aka Yet Another Resource Negotiator) is a framework to provide computational resources for execution engines like Map Reduce, Apache Spark, Apache Storm, Hive, Hbase, etc. As a key Hadoop component, YARN is responsible for allocating system resources (E.g. … Read more...
This content is for 30-Day-Full-Access, 100-Day-Full-Access, 200-Day-Full-Access, and 365-Day-Full-Access members only.
Register
80+ Free Java FAQs
80+ Free Big Data FAQs
Already a member? Log in here
5 Spark streaming & Apache storm Interview Q&As
Q116. What is “Spark streaming” in the Spark ecosystem with Spark core, Spark SQL, Spark MLlib, Spark GraphX, etc? A116. Spark is a distributed and scalable batch processing framework that supports in-memory processing in sub-seconds. The batch processes are scheduled with something like Oozie or Unix cron jobs to run...
This content is for 30-Day-Full-Access, 100-Day-Full-Access, 200-Day-Full-Access, and 365-Day-Full-Access members only.
Register
80+ Free Java FAQs
80+ Free Big Data FAQs
Already a member? Log in here
6 Delta Lake interview questions & answers
Q01. What is delta lake for Apache Spark? A01. Delta Lake is an open source storage layer that brings reliability to data lakes. It as a dependency JAR that needs to be added to your Apache Spark project. … Read more ›...
This content is for 30-Day-Full-Access, 100-Day-Full-Access, 200-Day-Full-Access, and 365-Day-Full-Access members only.
Register
80+ Free Java FAQs
80+ Free Big Data FAQs
Already a member? Log in here
6 LDAP Interview Q&As

Q1. What is an LDAP server? And what is it used for in an enterprise environment? A1. LDAP stands for Lightweight Directory Access Protocol. This is an extensible open network protocol standard that provides access to distributed directory services. … Read more ›...
This content is for 30-Day-Full-Access, 100-Day-Full-Access, 200-Day-Full-Access, and 365-Day-Full-Access members only.
Register
80+ Free Java FAQs
80+ Free Big Data FAQs
Already a member? Log in here
8 Apache Spark repartition Vs. coalesce scenarios interview Q&As
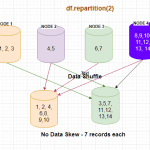
Q01: Why is partitioning of data required in Apache Spark?
A01: Partitioning is a key concept in distributed systems where the data is split into multiple partitions so that you can execute transformations on multiple partitions in parallel, which helps a job to finish faster.
…
8 Apache Spark streaming interview questions and answers
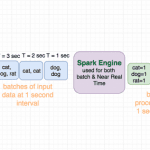
Q01 What is Spark streaming? A01 Spark streaming extends Spark core/sql to what is called a micro-batching to give Near-Real-Time processing where the arriving live stream of data from sources like Kafka, Kinesis, Flume, HDFS file system, etc divided into batches of predefined interval. … Read more ›...
This content is for 30-Day-Full-Access, 100-Day-Full-Access, 200-Day-Full-Access, and 365-Day-Full-Access members only.
Register
80+ Free Java FAQs
80+ Free Big Data FAQs
Already a member? Log in here
300+ Java Interview Questions - FAQs
10+ Companion Techs Interview Q&As
300+ Big Data Interview Questions - FAQs
16+ Java Tech Key Areas Interview Q&As
Your Career Tips to go places
Tutorials on Java & Big Data
300+ Java Interview Questions Answered
“
I have a good news, I got job offer. I like to share with you from my bottom of my heart feeling thankful to you.
Jithendra
via LinkedIn
Disclaimer
The contents in this Java-Success are copyrighted and from EmpoweringTech pty ltd. The EmpoweringTech pty ltd has the right to correct or enhance the current content without any prior notice. These are general advice only, and one needs to take his/her own circumstances into consideration. The EmpoweringTech pty ltd will not be held liable for any damages caused or alleged to be caused either directly or indirectly by these materials and resources. Any trademarked names or labels used in this blog remain the property of their respective trademark owners. Links to external sites do not imply endorsement of the linked-to sites. Privacy Policy
Responsive WordPress Theme
powered by
CyberChimps
Top
Scroll Up