*args and **kwargs are mostly used in function definitions. *args and **kwargs allow you to pass a variable number of arguments to a function. It is not necessary to write *args or **kwargs. Only the * (asterisk) is necessary. So, … Read more ›...
800+ Java & Big Data Interview Q&As
130+ job offers to choose from as a self-taught Java & Big Data contractor for 22+ years. It pays to prepare.
Blog Archives
11: Q88 – Q91 Read-Write Vs Append-Only File Systems
Q88. How will you modify a portion of an HDFS file? A88. HDFS is an “append-only” file system. The most common use case of Hadoop data ingestion is to append new sets of event-based and/or sub-transactional data. The large data processing applications are typically built around the premise that things...
This content is for 30-Day-Full-Access, 100-Day-Full-Access, 200-Day-Full-Access, and 365-Day-Full-Access members only.
Register
80+ Free Java FAQs
80+ Free Big Data FAQs
Already a member? Log in here
11a: 40+ Apache Spark best practices & optimisation interview FAQs – Part 1

There are so many different ways to solve the big data problems at hand in Spark, but some approaches can impact on performance, and lead to performance and memory issues. Here are some best practices to keep in mind when writing Spark jobs.
#1 Favor DataFrames,
…
11A: Scala values, proper types, first order types & higher kinded types
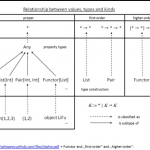
Q1. What is a proper type in Scala? A1. String, List[Int], List[String], Person, etc are proper types in Scala. The below diagram will become clearer at the end.
|
1 2 3 4 5 6 7 8 9 10 11 12 13 14 15 16 17 18 19 20 21 |
package com.sbthello object ProperType { val a: Int = 5 val b: String = "5" val list1: List[String] = List("1","2","3") val list2: List[Int] = List(1 ,2, 3) case class Person(name: String, age: Int) val p: Person = Person("John", 5) val map: Map[String, Int] = Map("Key1" -> 5, "Key2" -> 8) } |
Proper types are a higher level concept than values (E.g. … Read more ›...
This content is for 30-Day-Full-Access, 100-Day-Full-Access, 200-Day-Full-Access, and 365-Day-Full-Access members only.
Register
80+ Free Java FAQs
80+ Free Big Data FAQs
Already a member? Log in here
11b: 50+ Apache Spark best practices & optimisation interview FAQs – Part 2 Spark UI

This extends 40+ Apache Spark best practices & optimisation interview FAQs – Part-1, where best practices 1-10 were covered with examples & diagrams. #11 Use Spark UI: Running Spark jobs without inspecting the Spark UI is a definite NO. … Read more ›...
This content is for 30-Day-Full-Access, 100-Day-Full-Access, 200-Day-Full-Access, and 365-Day-Full-Access members only.
Register
80+ Free Java FAQs
80+ Free Big Data FAQs
Already a member? Log in here
11B: Q71 – Q72 – Scala type parameterization & variance interview Q&As
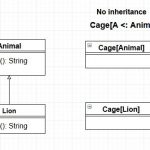
Q71. Does Scala have type erasure as in Java?
A71. Yes. Scala parametrized types loose the type information after compilation in the same way as Java does.
Q72a. What are different type parameter modifiers in Scala?
A72a.
Cage[T]
T is of any type
Invariance
Cage[T <: Animal]
T is sub type of an Animal
upper bound,
…
11c: 50+ Apache Spark best practices & optimisation interview FAQs – Part 3 Partitions & buckets
This extends 40+ Apache Spark best practices & optimisation interview FAQs – Part-2 Spark UI. #31 Bucketing is another data optimisation technique that groups data with the same bucket value across a fixed number of “buckets”. Bucketing improves performance in wide transformations and joins by minimising or avoiding data “shuffles”....
This content is for 30-Day-Full-Access, 100-Day-Full-Access, 200-Day-Full-Access, and 365-Day-Full-Access members only.
Register
80+ Free Java FAQs
80+ Free Big Data FAQs
Already a member? Log in here
11C: Q73 – Q77 – Scala type parameterization & variance interview Q&As
This extends the type parameters basics at 11B: Q71 – Q72 – Scala type parameterization & variance interview Q&As. Cage[T] T is of any type Invariance Cage[T <: Animal] T is sub type of an Animal upper bound, … Read more ›...
This content is for 30-Day-Full-Access, 100-Day-Full-Access, 200-Day-Full-Access, and 365-Day-Full-Access members only.
Register
80+ Free Java FAQs
80+ Free Big Data FAQs
Already a member? Log in here
11d: 50+ Apache Spark best practices & optimisation interview FAQs – Part 4 Small Files problem

Q38: What is the difference between repartition & Coalesce? A38: Repartition equally distributes the data across machines, hence requires reshuffling, hence slower than coalesce, but can improve the overall performance of the job as it can prevent data skewing by equally distributing the data across the executors. … Read more...
This content is for 30-Day-Full-Access, 100-Day-Full-Access, 200-Day-Full-Access, and 365-Day-Full-Access members only.
Register
80+ Free Java FAQs
80+ Free Big Data FAQs
Already a member? Log in here
11D: Scala existential type interview Q&As
Q01. What are existential types? A01. Existential types are a way of abstracting over types. They let you assert that some type “exists” without specifying exactly what it is as you don’t care what it is in the current context. For example, counting the number of elements in a list....
This content is for 30-Day-Full-Access, 100-Day-Full-Access, 200-Day-Full-Access, and 365-Day-Full-Access members only.
Register
80+ Free Java FAQs
80+ Free Big Data FAQs
Already a member? Log in here
11e: 50+ Apache Spark best practices & optimisation interview FAQs – Part 5 Cache Vs Persist Vs Checkpoint
This extends 50+ Apache Spark best practices & optimisation interview FAQs – Part 4 Small Files problem Q44 What do you understand by the terms caching, persisting & checkpointing with respect to Apache Spark? … Read more ›...
This content is for 30-Day-Full-Access, 100-Day-Full-Access, 200-Day-Full-Access, and 365-Day-Full-Access members only.
Register
80+ Free Java FAQs
80+ Free Big Data FAQs
Already a member? Log in here
11f: 50+ Apache Spark best practices & optimisation interview FAQs – Part 6 Serialization & UDFs
This extends 11e: 50+ Apache Spark best practices & optimisation interview FAQs – Part 5 Cache Vs Persist Vs Checkpoint. Q46 Why is serialization important in Spark? A46 Serialization and deserialization are important concepts in Apache Spark. … Read more ›...
This content is for 30-Day-Full-Access, 100-Day-Full-Access, 200-Day-Full-Access, and 365-Day-Full-Access members only.
Register
80+ Free Java FAQs
80+ Free Big Data FAQs
Already a member? Log in here
12 Apache Spark getting started interview questions and answers

Q01. Where is Apache Spark used in the Hadoop eco system? A01. Spark is essentially a data processing framework that is faster & more flexible than “Map Reduce”. The Spark itself has grown into an eco system with Spark SQL, Spark streaming, Spark UI, GraphX, … Read more ›...
This content is for 30-Day-Full-Access, 100-Day-Full-Access, 200-Day-Full-Access, and 365-Day-Full-Access members only.
Register
80+ Free Java FAQs
80+ Free Big Data FAQs
Already a member? Log in here
300+ Java Interview Questions - FAQs
10+ Companion Techs Interview Q&As
300+ Big Data Interview Questions - FAQs
16+ Java Tech Key Areas Interview Q&As
Your Career Tips to go places
Tutorials on Java & Big Data
300+ Java Interview Questions Answered
“
I have a good news, I got job offer. I like to share with you from my bottom of my heart feeling thankful to you.
Jithendra
via LinkedIn
Disclaimer
The contents in this Java-Success are copyrighted and from EmpoweringTech pty ltd. The EmpoweringTech pty ltd has the right to correct or enhance the current content without any prior notice. These are general advice only, and one needs to take his/her own circumstances into consideration. The EmpoweringTech pty ltd will not be held liable for any damages caused or alleged to be caused either directly or indirectly by these materials and resources. Any trademarked names or labels used in this blog remain the property of their respective trademark owners. Links to external sites do not imply endorsement of the linked-to sites. Privacy Policy
Responsive WordPress Theme
powered by
CyberChimps
Top
Scroll Up