Blog Archives
1 … 15 16 17 18 19 20 21 22 23

30: Python coding questions – removing duplicates & write a program

You can either set up your Python environment or use an online interpreter like www.online-python.com. Q01. How will you remove duplicates from a list?

A01. You can add it to a dictionary to remove the duplicates as shown below:

Outputs:

Q02. … Read more ›...

This content is for 30-Day-Full-Access, 100-Day-Full-Access, 200-Day-Full-Access, and 365-Day-Full-Access members only. Register 80+ Free Java FAQs 80+ Free Big Data FAQs
Already a member? Log in here


31: 50+ SQL scenarios based interview Q&As – Finding records from first table where no match found in second table

Setup the data on db-fiddle MySQL V9.0 to practice. There are business scenarios for:

1) Finding records in the first table where matching records are found in the second table are shown in the output. This can be done with a semi-join.

…

Read more ›


31: Python coding questions – characters by frequency, anagrams, recursion, etc

You can either set up your Python environment or use an online interpreter like www.online-python.com. Q01. How will you sort a word by frequency of its characters? Input: TREE Output: EETR A01. … Read more ›...

This content is for 30-Day-Full-Access, 100-Day-Full-Access, 200-Day-Full-Access, and 365-Day-Full-Access members only. Register 80+ Free Java FAQs 80+ Free Big Data FAQs
Already a member? Log in here


32: 50+ SQL scenarios based interview Q&As – use of unpivot, lag(..), row_num(..), cumulative sum() and CTE

Setup the data on db-fiddle MySQL V9.0 to practice. Make sure to select latest MySQL version to ensure Common Table Expressions (i.e CTE) is supported. This is not a real life scenario problem, but a simple example that uses many of the SQL syntaxes & techniques. … Read more ›...

This content is for 30-Day-Full-Access, 100-Day-Full-Access, 200-Day-Full-Access, and 365-Day-Full-Access members only. Register 80+ Free Java FAQs 80+ Free Big Data FAQs
Already a member? Log in here


32: Python coding questions – Error Handling & Logging

You can either set up your Python environment or use an online interpreter like www.online-python.com. Q01. How do you handle errors in Python? A01. In Python, exceptions are errors detected during execution. … Read more ›...

This content is for 30-Day-Full-Access, 100-Day-Full-Access, 200-Day-Full-Access, and 365-Day-Full-Access members only. Register 80+ Free Java FAQs 80+ Free Big Data FAQs
Already a member? Log in here


33: 50+ SQL scenarios based interview Q&As – Nuances of NULL in SQL

NULL is a special marker used in SQL to indicate that a data value does not exist in the database.

Setup the data on db-fiddle MySQL V9.0 to practice. Make sure to select latest MySQL version to ensure Common Table Expressions (i.e CTE) is supported.

…

Read more ›


33: Python coding questions – file operations & handling large files

Q01. What are the challenges in handling large files in Python? A01. The challenges with handling large files involve: 1) Memory Usage: Trying to load a large file say a 64 GB entirely into memory can lead to slow performance of an application due to lack of memory, … Read...

This content is for 30-Day-Full-Access, 100-Day-Full-Access, 200-Day-Full-Access, and 365-Day-Full-Access members only. Register 80+ Free Java FAQs 80+ Free Big Data FAQs
Already a member? Log in here


5 Amazon EMR Vs. Cloudera interview Q&As

Q1. What is Amazon EMR? A1. EMR stands for Elastic Map Reduce, which is an Amazon Web Services (AWS) tool for big data processing and analysis. Amazon EMR offers elastic, cost-effective, and expandable low-configuration service as an alternative to running an on premise or EC2 cloude based Hadoop cluster (E.g....

This content is for 30-Day-Full-Access, 100-Day-Full-Access, 200-Day-Full-Access, and 365-Day-Full-Access members only. Register 80+ Free Java FAQs 80+ Free Big Data FAQs
Already a member? Log in here


5 Apache YARN interview Q&As

Q1. What is Apache YARN? A1. Apache Hadoop YARN (aka Yet Another Resource Negotiator) is a framework to provide computational resources for execution engines like Map Reduce, Apache Spark, Apache Storm, Hive, Hbase, etc. As a key Hadoop component, YARN is responsible for allocating system resources (E.g. … Read more...

This content is for 30-Day-Full-Access, 100-Day-Full-Access, 200-Day-Full-Access, and 365-Day-Full-Access members only. Register 80+ Free Java FAQs 80+ Free Big Data FAQs
Already a member? Log in here


5 Spark streaming & Apache storm Interview Q&As

Q116. What is “Spark streaming” in the Spark ecosystem with Spark core, Spark SQL, Spark MLlib, Spark GraphX, etc? A116. Spark is a distributed and scalable batch processing framework that supports in-memory processing in sub-seconds. The batch processes are scheduled with something like Oozie or Unix cron jobs to run...

This content is for 30-Day-Full-Access, 100-Day-Full-Access, 200-Day-Full-Access, and 365-Day-Full-Access members only. Register 80+ Free Java FAQs 80+ Free Big Data FAQs
Already a member? Log in here


6 Delta Lake interview questions & answers

Q01. What is delta lake for Apache Spark? A01. Delta Lake is an open source storage layer that brings reliability to data lakes. It as a dependency JAR that needs to be added to your Apache Spark project. … Read more ›...

This content is for 30-Day-Full-Access, 100-Day-Full-Access, 200-Day-Full-Access, and 365-Day-Full-Access members only. Register 80+ Free Java FAQs 80+ Free Big Data FAQs
Already a member? Log in here


6 LDAP Interview Q&As

Q1. What is an LDAP server? And what is it used for in an enterprise environment? A1. LDAP stands for Lightweight Directory Access Protocol. This is an extensible open network protocol standard that provides access to distributed directory services. … Read more ›...

This content is for 30-Day-Full-Access, 100-Day-Full-Access, 200-Day-Full-Access, and 365-Day-Full-Access members only. Register 80+ Free Java FAQs 80+ Free Big Data FAQs
Already a member? Log in here


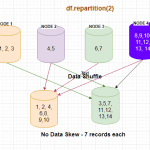
8 Apache Spark repartition Vs. coalesce scenarios interview Q&As

Q01: Why is partitioning of data required in Apache Spark?
A01: Partitioning is a key concept in distributed systems where the data is split into multiple partitions so that you can execute transformations on multiple partitions in parallel, which helps a job to finish faster.

…

Read more ›


1 … 15 16 17 18 19 20 21 22 23

300+ Java Interview Questions - FAQs

Tutorials on Java & Big Data